Back to Projects
Computer Vision

DeepScan — Deepfake Video Detection

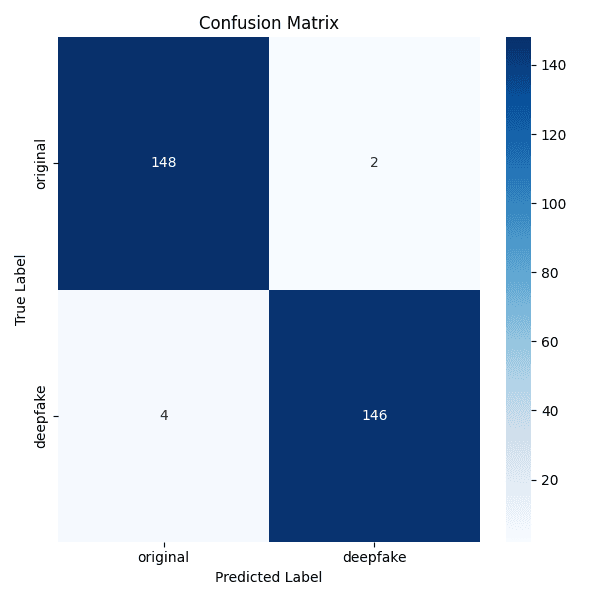
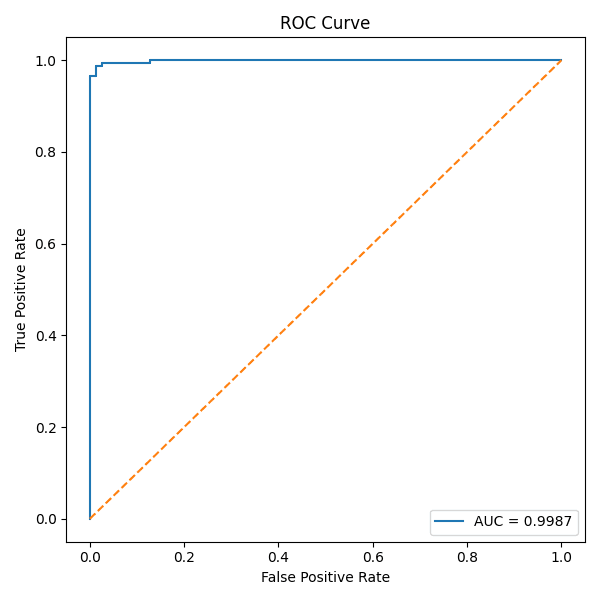
End-to-end deepfake detection system combining EfficientNet-B4 + Transformer Encoder with temporal attention — 98% accuracy, 99.87% ROC AUC on 300-video hold-out test set

98% accuracy
Eval Score
< 2s/video
Latency
300 videos
Dataset
On-device
Cost/call
System Overview

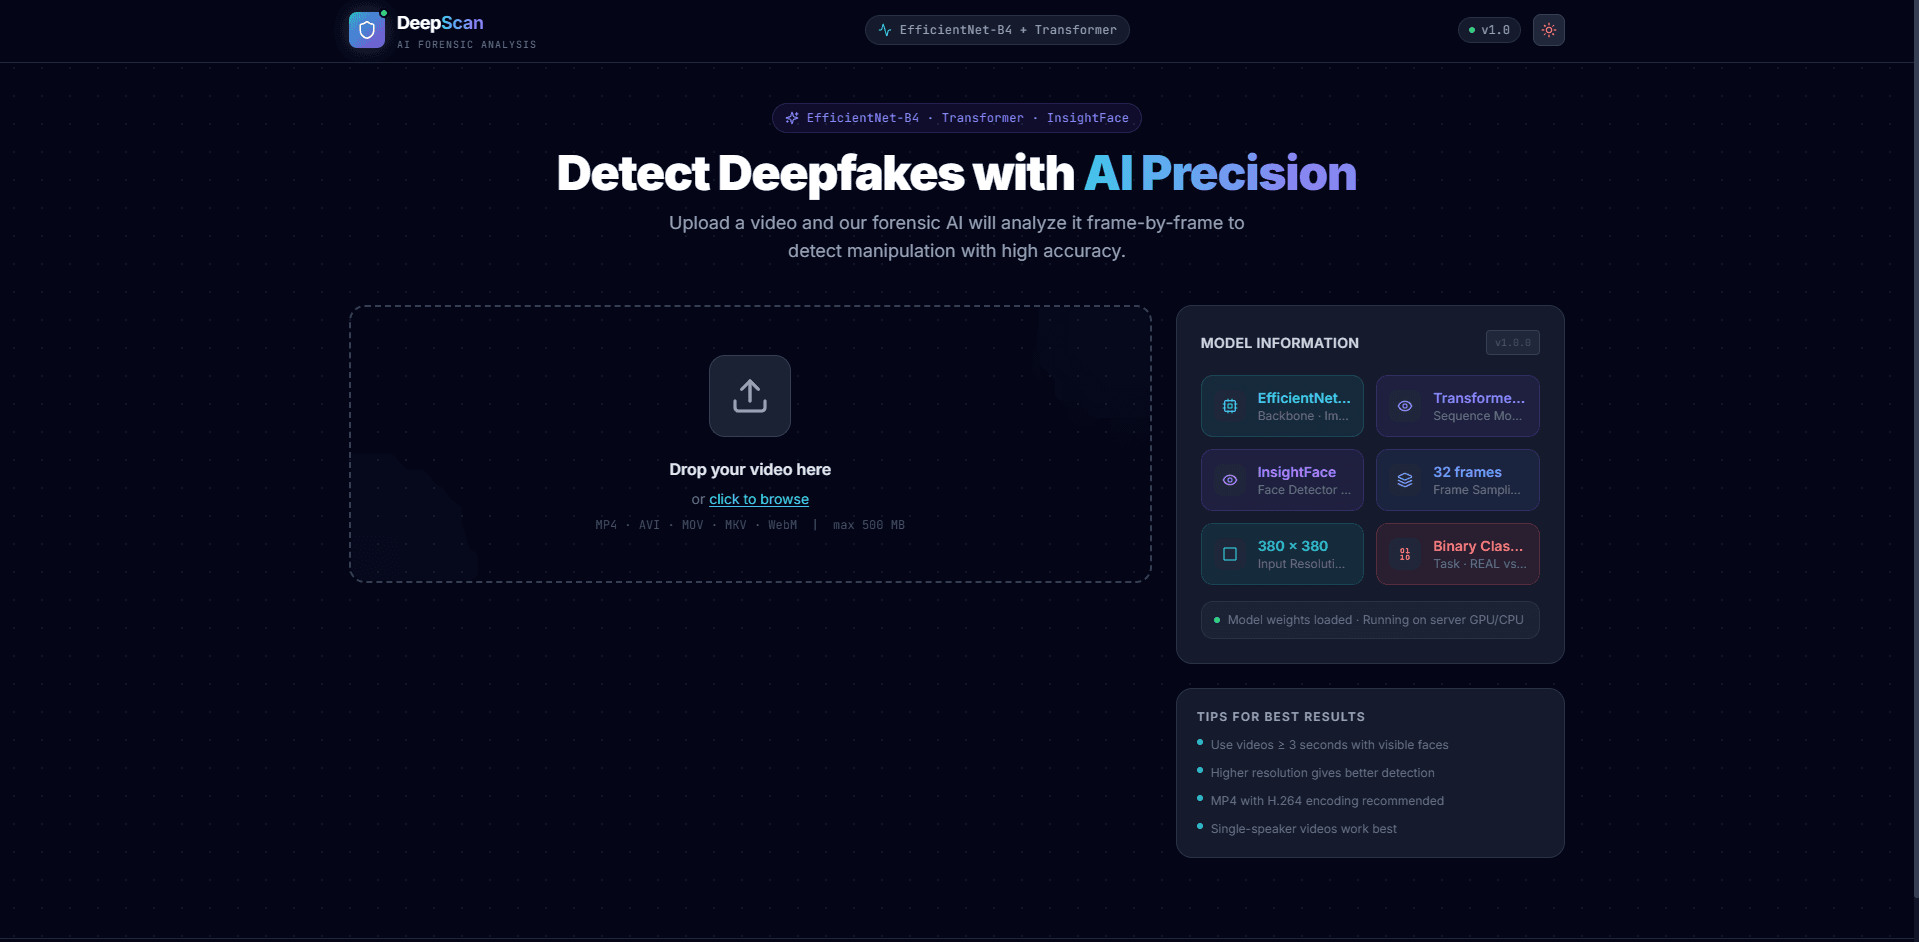
DeepScan is a complete end-to-end deepfake detection solution for both research and production. It converts raw video into a forensic prediction by combining a video processing pipeline that extracts frames and crops faces, a hybrid spatio-temporal deep learning model, and a FastAPI backend + React frontend dashboard for upload, prediction, explainability, and results tracking.

The system accepts a video upload, detects and crops faces using InsightFace (buffalo_l), extracts spatial features using EfficientNet-B4, and models temporal relationships across frames with a Transformer Encoder. Temporal attention is used to identify the most influential frames, producing a final REAL / DEEPFAKE prediction with confidence scores.

The production inference pipeline samples 32 frames uniformly, detects faces with InsightFace, builds the input tensor, and runs forward_with_attention() to get logits and temporal attention weights. The top 5 most influential frames are extracted for explainability, with frame-level scores and timestamps surfaced in the UI. The model was rigorously tested on a hold-out test dataset of 300 videos (150 Real, 150 Deepfake).

Architecture
Video Input
    │
    ▼
┌─────────────────────────────┐
│  Frame Extraction (32 fps)  │  ← Uniform sampling
└──────────────┬──────────────┘
               │
    ▼
┌─────────────────────────────┐
│ InsightFace (buffalo_l)     │  ← Face detection & crop
└──────────────┬──────────────┘
               │  380×380 face crops
    ▼
┌─────────────────────────────┐
│ EfficientNet-B4 Backbone    │  ← 1792-dim spatial features/frame
└──────────────┬──────────────┘
               │  Project → 512-dim
    ▼
┌─────────────────────────────┐
│ Transformer Encoder (6L×8H) │  ← Sinusoidal positional encoding
└──────────────┬──────────────┘
               │
    ▼
┌─────────────────────────────┐
│ Temporal Attention MLP      │  ← Frame importance weights
└──────────────┬──────────────┘
               │  Weighted aggregation
    ▼
┌─────────────────────────────┐
│ Classifier Head             │  ← BN → ReLU → Dropout → Linear
└──────────────┬──────────────┘
               │
    ▼
  REAL / DEEPFAKE + Confidence
Tech Stack
PyTorchEfficientNet-B4Transformer EncoderInsightFaceFastAPIReactPythontimmAdamWCosineAnnealingLR
Key Highlights
Hybrid spatio-temporal model: EfficientNet-B4 backbone + 6-layer Transformer Encoder with 8 attention heads
98.00% accuracy / 99.87% ROC AUC on a 300-video hold-out test set
Temporal attention mechanism identifies and ranks the most influential frames per video
InsightFace buffalo_l face detection with automatic largest-face selection per frame
FastAPI backend + React frontend with explainability dashboard and prediction history
Mixed-precision training (GradScaler) + CosineAnnealingLR scheduling + gradient clipping
Full checkpoint/resume support — saves model, optimizer, scheduler, scaler, and training history
Detailed logging per pipeline stage for debugging, reproducibility, and production observability
Evaluation Metrics
98%
Accuracy
98.65%
Precision
97.33%
Recall
97.99%
F1-Score
99.87%
ROC AUC
Model Evaluation Reports
Confusion Matrix
Confusion Matrix
ROC Curve (AUC = 0.9987)
Training History
Training History
[01]Low-quality or very short videos with fewer than 32 detectable faces — mitigated by padding sequences with the final valid face crop
[02]Deepfakes with minimal facial movement across frames — temporal attention spreads weights too uniformly, reducing interpretability
[03]Extreme head angles or heavy occlusion confuse InsightFace face detection — addressed by falling back to the full frame when no face is found
What I Learned
[01]Hybrid Spatio-Temporal Modeling — designing a two-stage architecture that combines CNN spatial feature extraction with Transformer temporal modeling
[02]Temporal Attention — implementing a learnable attention mechanism to assign importance weights across a frame sequence for both prediction and explainability
[03]Transfer Learning at Scale — loading EfficientNet-B4 ImageNet weights via timm and fine-tuning only the final 25% of parameters
[04]Mixed Precision Training — using GradScaler and autocast for efficient GPU utilization and stable training
[05]Robust Training Pipeline — CosineAnnealingLR scheduling, gradient clipping, early stopping, and full checkpoint/resume support
[06]Production ML System Design — FastAPI + React integration, logging per pipeline stage, explainability surfacing in the UI
Project Preview
screenshot 1
1 / 4
thumb 1
thumb 2
thumb 3
thumb 4